Agibot’s WITA-Omni AI model accepts audio, video, touch and robot-state inputs, and can produce speech, motion and facial expressions. It targets physical robot interaction.
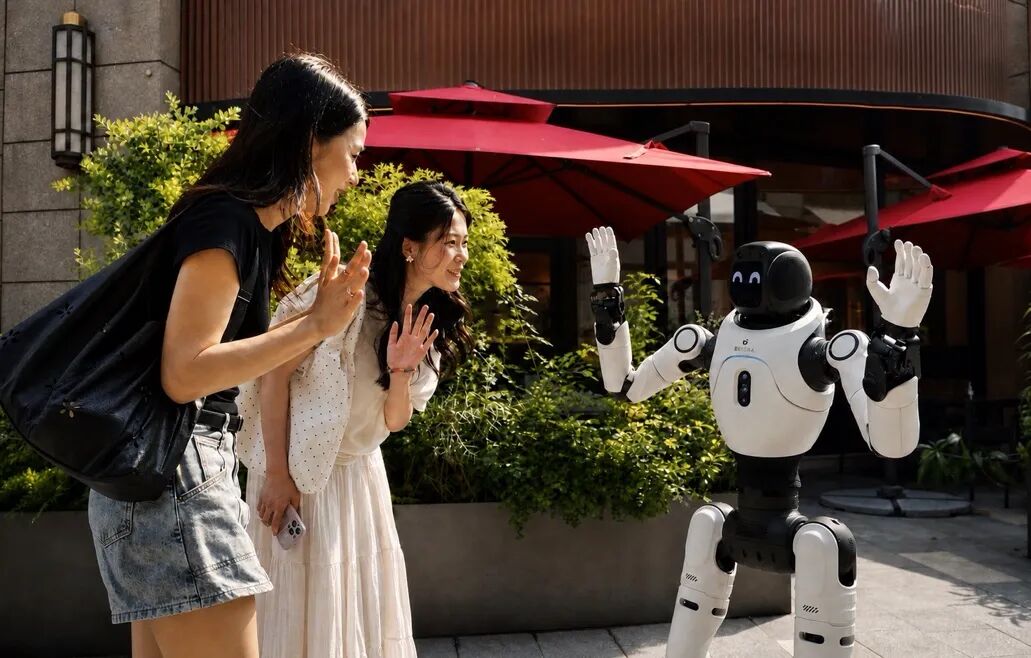
Photo source: IT之家 — illustrative robot photograph
The developer claims full-duplex conversation, responses from 400ms, wake-word-free interaction and over 100 languages and dialects. These are company claims, not independently tested results.