
Training and inference: the two stages of a neural network's life
Training is the stage when a neural network learns from huge datasets. Inference is the stage of using an already trained model: it receives a request and produces an answer.
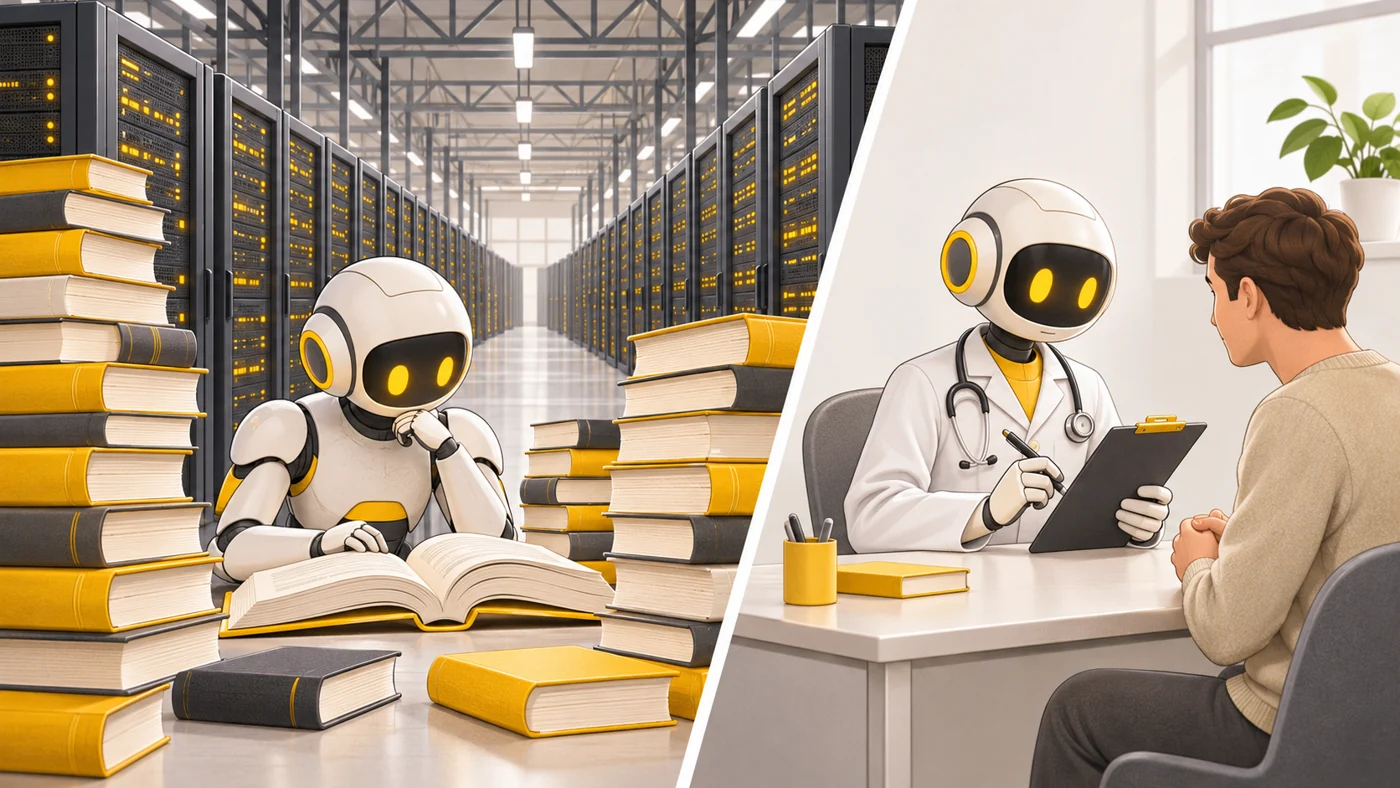
In plain words
Training is years of school and university: long, expensive, with piles of textbooks. Inference is the job after graduation: a doctor looks at a patient and makes a diagnosis in a minute. They do not relearn medicine every time - they use what they already know.
How it works
- During training, the model is run through the data millions of times and its parameters are adjusted.
- This is done in data centres on thousands of accelerators, sometimes for months.
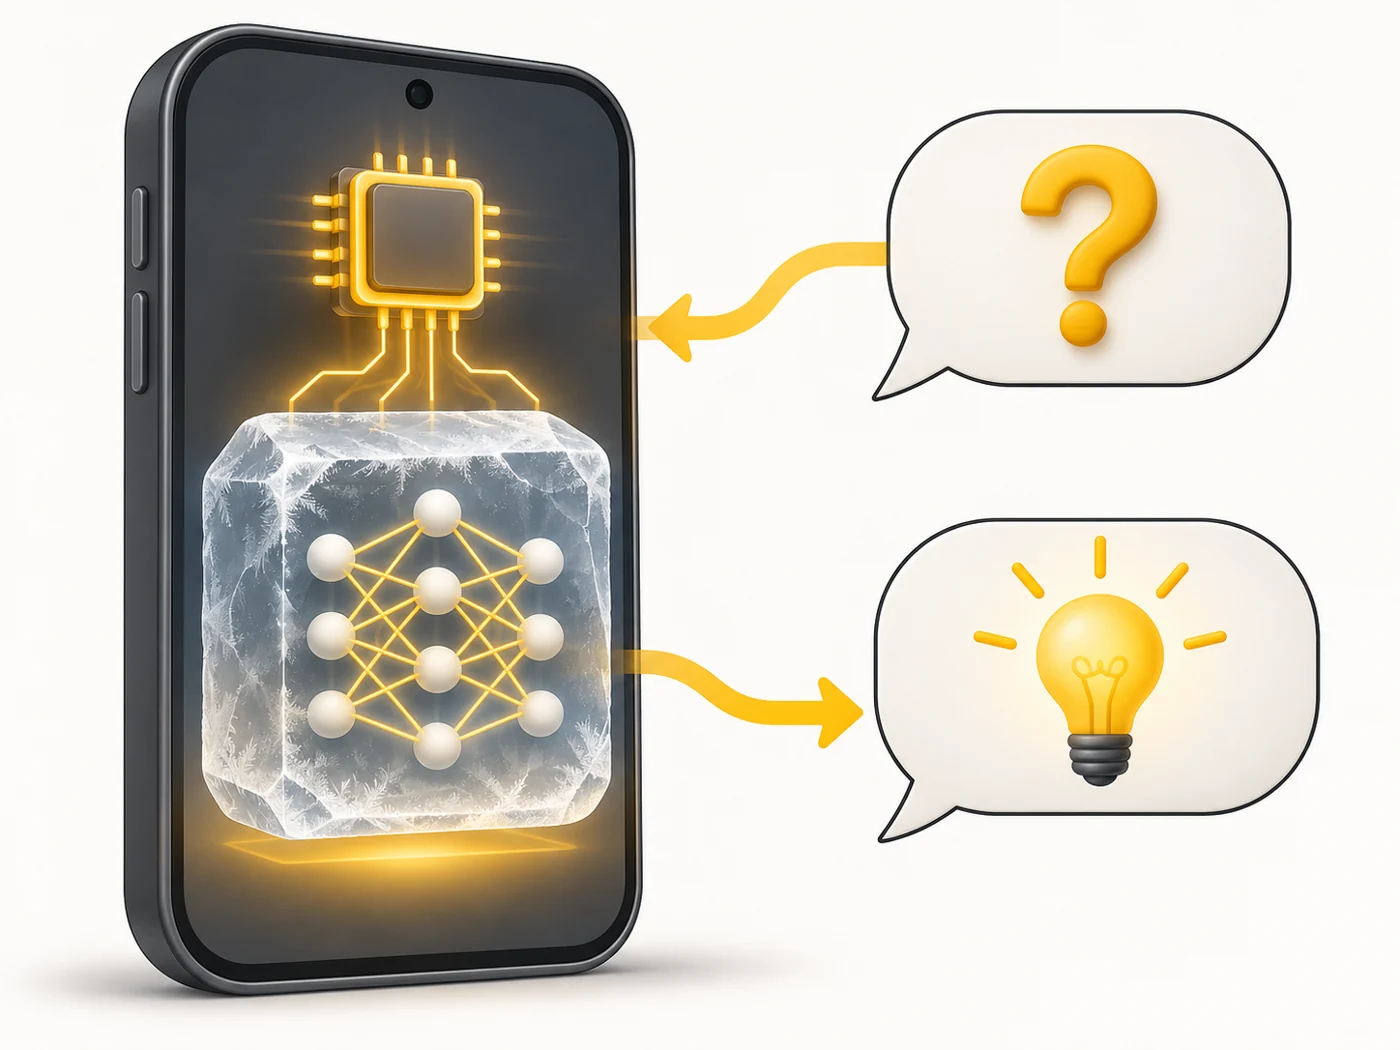
- After training, the parameters are "frozen" - the model is ready.
- Inference is one pass of a request through the finished model, without changing its parameters.
- Inference can run in the cloud or right on your phone if the model is small.
Where you'll see it
When a manufacturer says an AI feature runs "on device", they mean inference - the model was trained earlier, on servers. The neural processor (NPU) in a smartphone is built mainly for inference. And news about "the biggest AI data centres" is mostly about training.
Does it matter when buying
Knowing this helps you see through marketing. Your phone does not "learn" from scratch - it runs a ready-made model. That is why NPU speed and the amount of RAM matter: the model has to fit and respond quickly. For most people, cloud inference is fine too, if you have internet and do not mind sending your data.
Myths
- Myth: The model learns from every conversation I have. Reality: Usually not - parameters do not change during inference. Services may use conversations for future training, but that is a separate process and you can often turn it off.
- Myth: Inference is cheap. Reality: One request is, but billions of requests a day cost companies a huge amount of energy.
FAQ
Which is more expensive - training or inference?
Training one big model is very expensive, but inference for millions of users can end up costing even more over time.
Can a phone further train a model?
Only a little and in specific cases - for example, the keyboard adapts to your words.
What is an "AI accelerator"?
A special chip for neural network computations - from the NPU in a phone to big server boards.
Related terms
Neural Processing Unit (NPU), On-device AI, Cloud AI, Fine-tuning, Model parameters